
llama.cpp (Intel)
ggml-org
Run local language models on Intel hardware
已复制!粘贴到终端并按回车即可安装。
关于
A community package of the unmodified official llama.cpp OpenVINO build for local language model inference, an HTTP API and a browser chat interface. Model downloads have their own licenses.
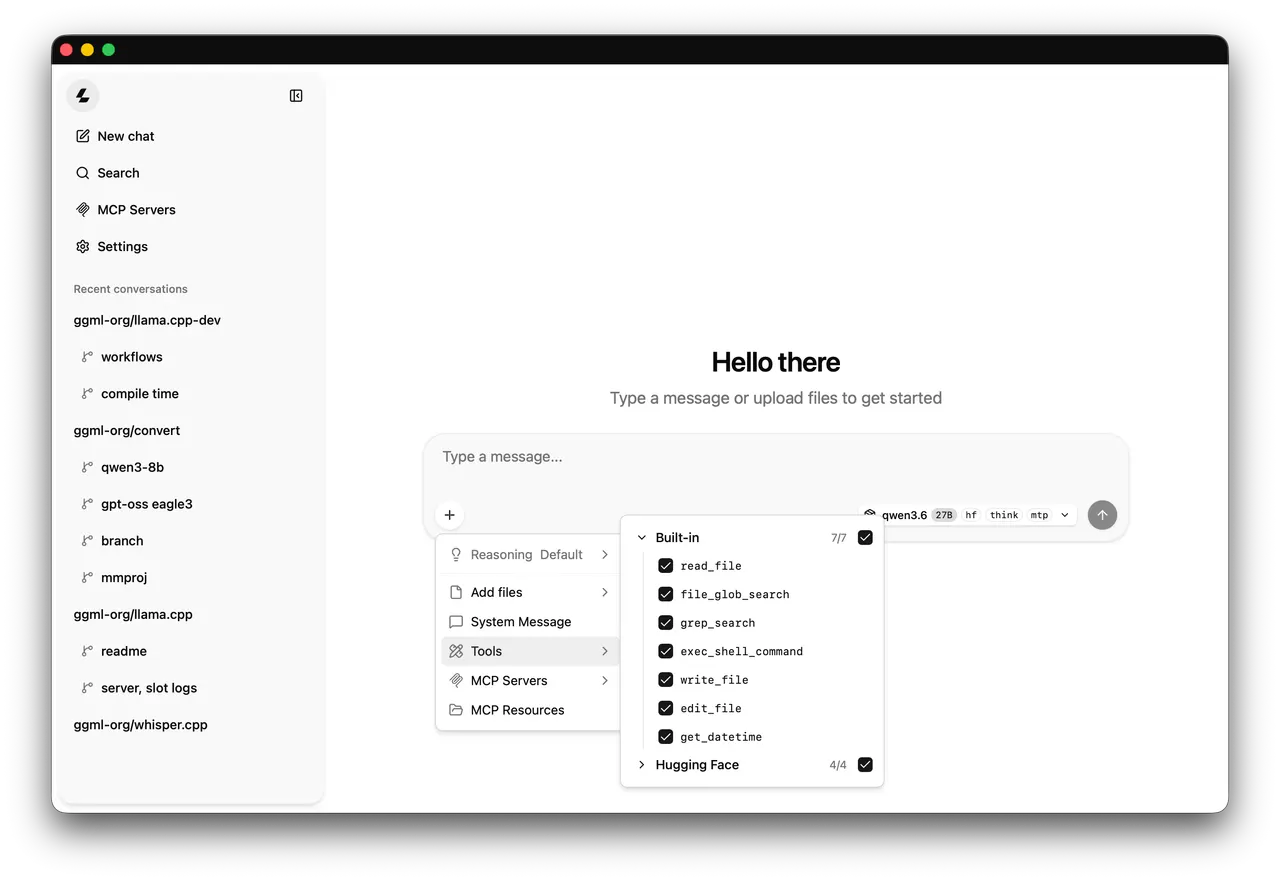
The desktop entry starts llama-server in a terminal. Open http://127.0.0.1:8084 in your browser. Models downloaded by llama.cpp stay in this app's private persistent cache. With no model argument, the server starts in router mode for cached models. Download a model first using the CLI, for example: flatpak run --command=llama-cli io.github.ggml_org.LlamaCpp.OPENVINO -hf bartowski/Qwen_Qwen3-0.6B-GGUF:Q4_K_M -c 512
Command line tools are available with flatpak run --command=llama-cli io.github.ggml_org.LlamaCpp.OPENVINO, and similarly llama, llama-bench and llama-quantize. Include -fa 1 when using llama-bench with the OpenVINO backend. Pass server model and port options after flatpak run io.github.ggml_org.LlamaCpp.OPENVINO. The Intel edition uses its own default port (8084) and private cache.
Host model directories are optional. Grant only a directory you need: flatpak override --user --filesystem=/path/to/models:ro io.github.ggml_org.LlamaCpp.OPENVINO. Then pass -m /path/to/models/model.gguf. To remove overrides: flatpak override --user --reset io.github.ggml_org.LlamaCpp.OPENVINO.
Python model conversion and workflows requiring a host toolchain are not included.
OpenVINO selects the Intel CPU by default. List devices with flatpak run --command=llama-cli io.github.ggml_org.LlamaCpp.OPENVINO --list-devices. Model and operation support depends on the upstream OpenVINO backend; start with a small context such as -c 512.
Intel GPU and NPU inference require compatible drivers and separate hardware testing. GPU access is optional: flatpak override --user --device=dri io.github.ggml_org.LlamaCpp.OPENVINO. Select it with flatpak run --env=GGML_OPENVINO_DEVICE=GPU io.github.ggml_org.LlamaCpp.OPENVINO. NPU access additionally requires flatpak override --user --device=all io.github.ggml_org.LlamaCpp.OPENVINO, which exposes all host devices; select it with flatpak run --env=GGML_OPENVINO_DEVICE=NPU io.github.ggml_org.LlamaCpp.OPENVINO. These accelerators have not been validated in this package. Reset grants with flatpak override --user --reset io.github.ggml_org.LlamaCpp.OPENVINO.
详情
权限
1 项需确认网络访问
可访问互联网和本地网络